Figure "Helix 2.5": zero-shot generalization across 30 unseen homes
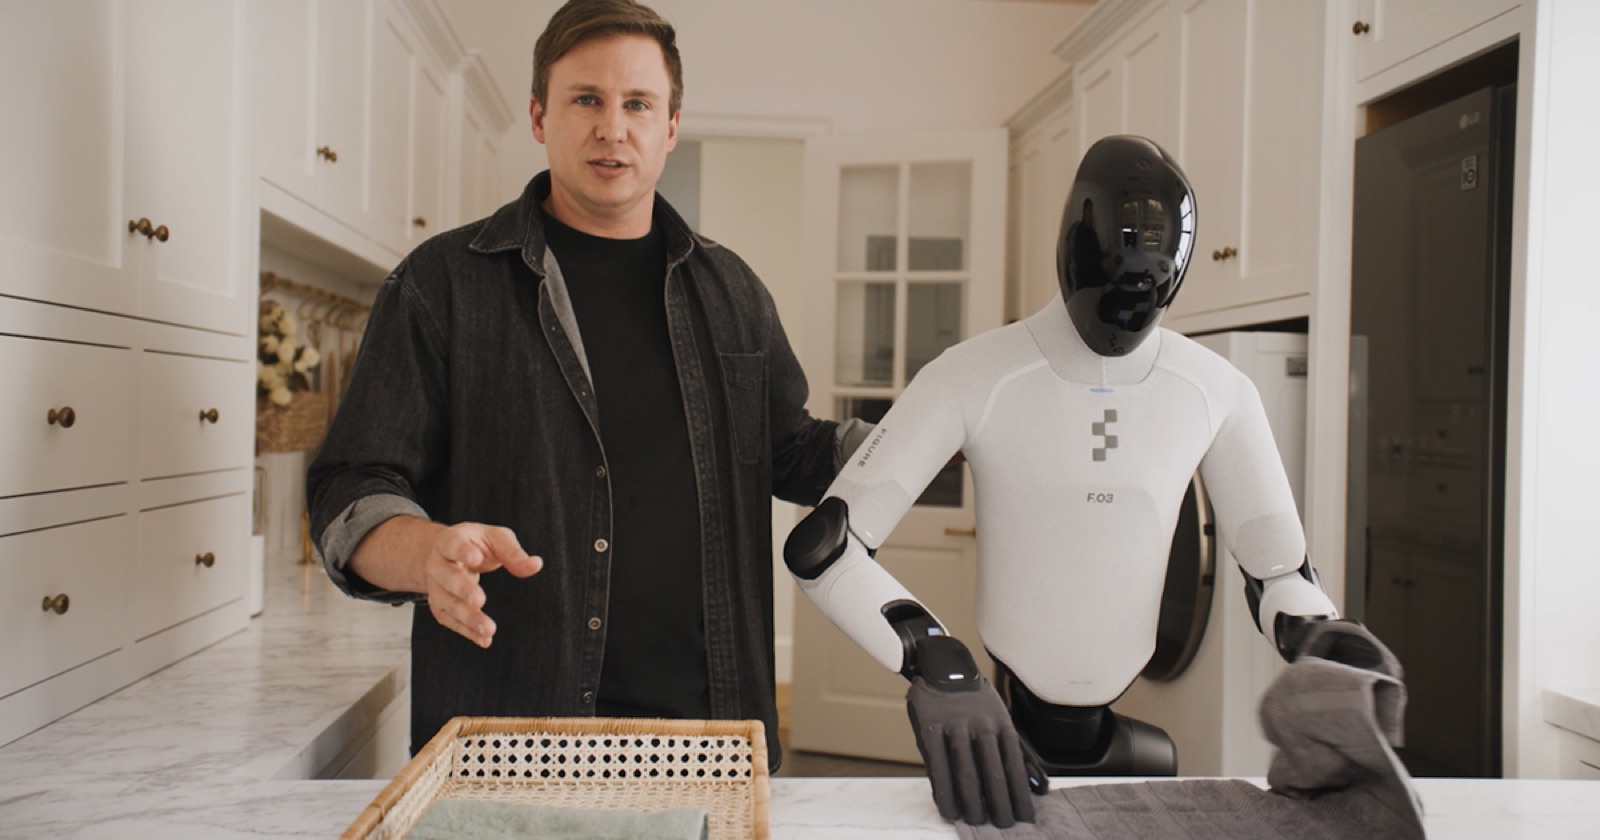
Something people take for granted — and robots cannot do
On September 17, Figure introduced Helix 2.5, its next-generation humanoid control model — in the company's words, the most advanced neural network it has built. The question it answers sounds almost mundane: a person can walk into an unfamiliar home and start working immediately, without relearning how to make a bed because it is a different height or how to tidy a room because the furniture changed. Robots have not worked that way. They learn the places they work in, one place at a time.
Helix 02, the previous generation, had already shown that a neural policy could coordinate an entire humanoid body over long horizons — unloading a dishwasher, or running a logistics task autonomously for 200 hours. But those systems learned from data collected in the very places where the robots would operate. Helix 2.5 tries to cross that line: one foundation model pretrained on Index, Figure's dataset of human behavior, supporting homes the robot has never entered.
From 9% to 56%: changing exactly one variable
From a single Index-pretrained base model, Figure derived three behaviors: tidying living rooms, folding towels and making beds. Then it took the robot into 30 Bay Area homes. Together the tasks exercise perception, locomotion, manipulation, bimanual coordination and whole-body control: tidying means picking up all 13 to 15 scattered toys and placing them in a basket, folding means folding towels and putting them in a basket, and bed making means placing both pillows and both comforter corners at the top of the bed with the comforter pulled smooth.
Zero-shot here has a strict definition: every home and every manipulated object was absent from the task-specification data, and the robot used each home's existing couches, beds and folding surfaces. Evaluation objects were set aside before any experiment began, and an AI model followed by human review confirmed they never appeared in task-specification data. A single fixed checkpoint ran all 30 homes; no weights were adapted to a home or an object, and checkpoint selection never looked at evaluation rollouts.
The decisive control experiment changed exactly one variable. Figure trained two policies on identical task-specification data — which likewise excluded the evaluation homes and objects. One was initialized with random weights; the other started from the Index-pretrained Helix 2.5. Architecture, optimizer, hyperparameters, downstream data and evaluation were held fixed. The only difference was Index pretraining.
In blind evaluation the from-scratch policy succeeded on 9% of zero-shot trials; the Index-pretrained policy succeeded on 56% — more than six times higher. Figure concludes that most of Helix 2.5's zero-shot capability comes from Index pretraining rather than the task-specification data itself. One number illustrates how broad that pretraining is: no single evaluation task accounts for more than 1.90% of the Index pretraining set. The starting points differ too — Helix 02 began from a pretrained vision-language model, while Helix 2.5 was pretrained entirely on Index from random initialization.
The success bar is equally strict: the whole task must be completed — every toy in the basket, every towel folded, the whole bed made. Figure gives no partial credit. The rubric was fixed before evaluation began: each toy has a one-minute timeout, after which the trial is aborted; each towel has a three-minute timeout and is graded A, B or C by whether its four corners end up within an inch of one another; a pillow must be picked up and placed on the top third of the bed, with under 15 degrees of orientation error graded good and under 45 degrees graded bad; both sides of the comforter must be lifted and both corners must reach the top third, with corners within six inches graded good and six to twelve inches graded bad. Any trial requiring human intervention for safety is aborted and marked failed.
Half the data, self-correction, and a scaling curve
Did pretraining change how much robot data a new behavior requires? Figure compared Helix 2.5 with an earlier Helix 02 policy trained for the same task. The older policy's data was collected directly in the environment where it was evaluated; Helix 2.5 matched its success rate using half as much adaptation data — and did so zero-shot across 30 unseen homes. In Figure's phrasing: specifying a behavior cost half as much, while its scope expanded 30-fold.
Pretraining also produced a qualitative change: whole-body self-correction. Over long horizons, especially in unfamiliar settings, a robot will get a step wrong. Helix 2.5 steps back to reposition, changes its stance, or walks around a full bed to redo a fold. Figure treats this ability to recover and keep making progress as an effect of Index pretraining rather than a skill trained on purpose.
Scaling laws once transformed language-model development: next-token prediction error falls predictably as data and compute grow, so small runs can forecast large ones. Figure asked whether human-to-robot transfer behaves the same way. It trained four models on nested subsets of Index spanning an 8x increase in pretraining data, holding model size and downstream training fixed, fine-tuning each on the same task data and evaluating on the same held-out action-prediction loss. Loss fell as expected with each doubling. Predictability was the sharper result: using only the smaller runs, Figure forecast the largest run's test loss to four decimal places before training began, with a forecasting error equal to just 0.54% of the variation across the full 8x range. Figure calls it the first human-to-robot transfer scaling law measured on a humanoid — one that measures data scaling alone.
Why a home is a harder exam
Most robot generalization research happens in settings built around the machine: tabletop arms get a fixed workspace, wheeled robots need enough open floor for a base to fit and turn. A home offers no such accommodation. A humanoid must move through it as part of the task, positioning its body through tight, cluttered paths in order to see, reach and manipulate. The task therefore becomes a whole-body problem — perception, locomotion and manipulation cannot be solved separately. Zero-shot raises the bar again: the room, layout and objects were never seen in training, and there is no adaptation period on arrival, so the robot must solve the full perception-and-control problem with what it already knows — and autonomous humanoid behavior at this complexity is rare even in familiar environments.
How Index is organized matters. Figure characterizes tasks two ways: video embeddings of every clip, plus text embeddings of a vision-language model's per-segment activity and object descriptions. Both are clustered into a nested hierarchy of semantic groups, and the hours in any dataset or training snapshot are then measured against those groups. That broad pretraining is what supports fine-tuning for arbitrary behaviors, and it is the basis for Figure's claim to be the first to achieve zero-shot whole-body generalization at this scope.
The doubts deserve equal space. These are company-run results, not an independently reproduced benchmark, and Figure itself stresses that general humanoid robotics is far from solved. Zero-shot here refers to the evaluation environments and manipulated objects; the three tasks themselves were still specified by fine-tuning data collected elsewhere. Fifty-six percent means nearly half of the full tasks were not completed — for a home setting, that points a direction more than it proves usability.
Figure's next step is the recipe that already looks familiar from large language models: learn broadly in pretraining, specify a behavior once, and generalize at deployment. The company says Index is now gaining roughly 35 minutes of new human experience every second, backed by a $3.5B compute commitment to training Helix. A year ago, Figure argued that robotics was off by multiple orders of magnitude in model size, compute and especially data. Index and Helix 2.5 are its answer.